DeepInfer:支持多平台的高性能推理引擎
技术解密:吞吐、成本与延迟的极致优化
吞吐线:最小化GPU空转
- Prefill:四级调度共用代价模型,决策归结为compute-quota。
- Decode:两维均衡,moe_lb为1.090。
- Vision Encoder:按patch粒度分配,通常单卡部署。
- EP:采用冗余专家参数与动态重排。
- DSpark变长验证:利用低秩logit bias校正偏差,Confidence Head根据置信度决定验证长度,替代固定5 token验证,提升6%吞吐。
成本线:最小化重复Prefill
延迟线:TTFT与TBT分别优化
开源资源与说明
https://zhuanlan.zhihu.com/p/2095560295930508953
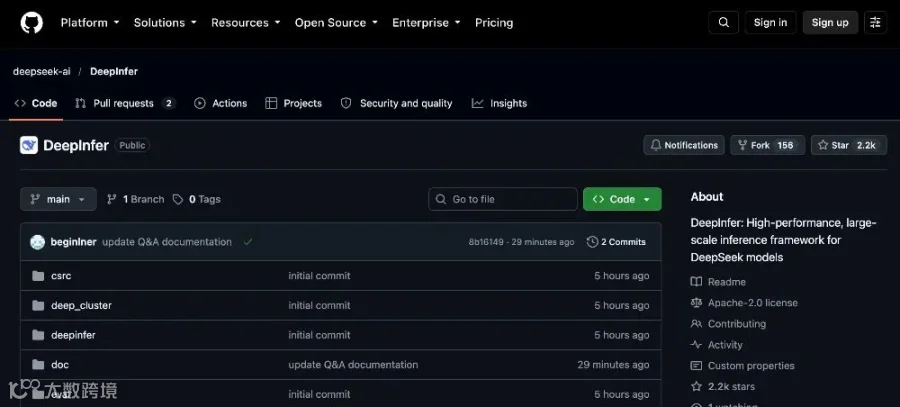
DeepInfer: https://github.com/deepseek-ai/DeepInfer
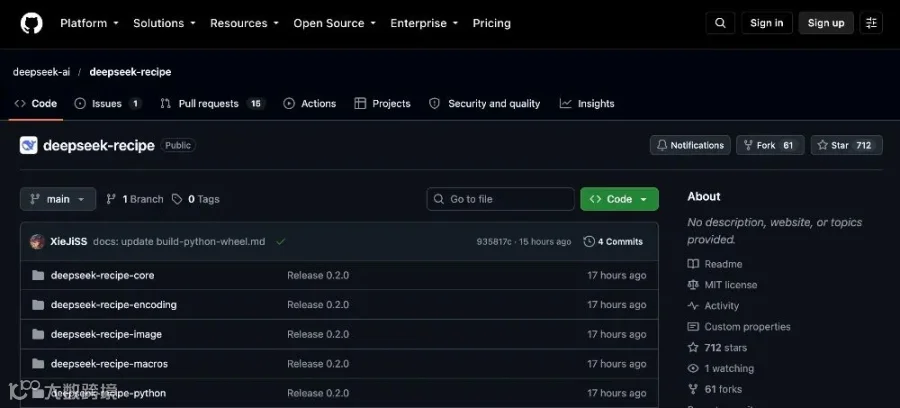
deepseek-recipe: https://github.com/deepseek-ai/deepseek-recipe